
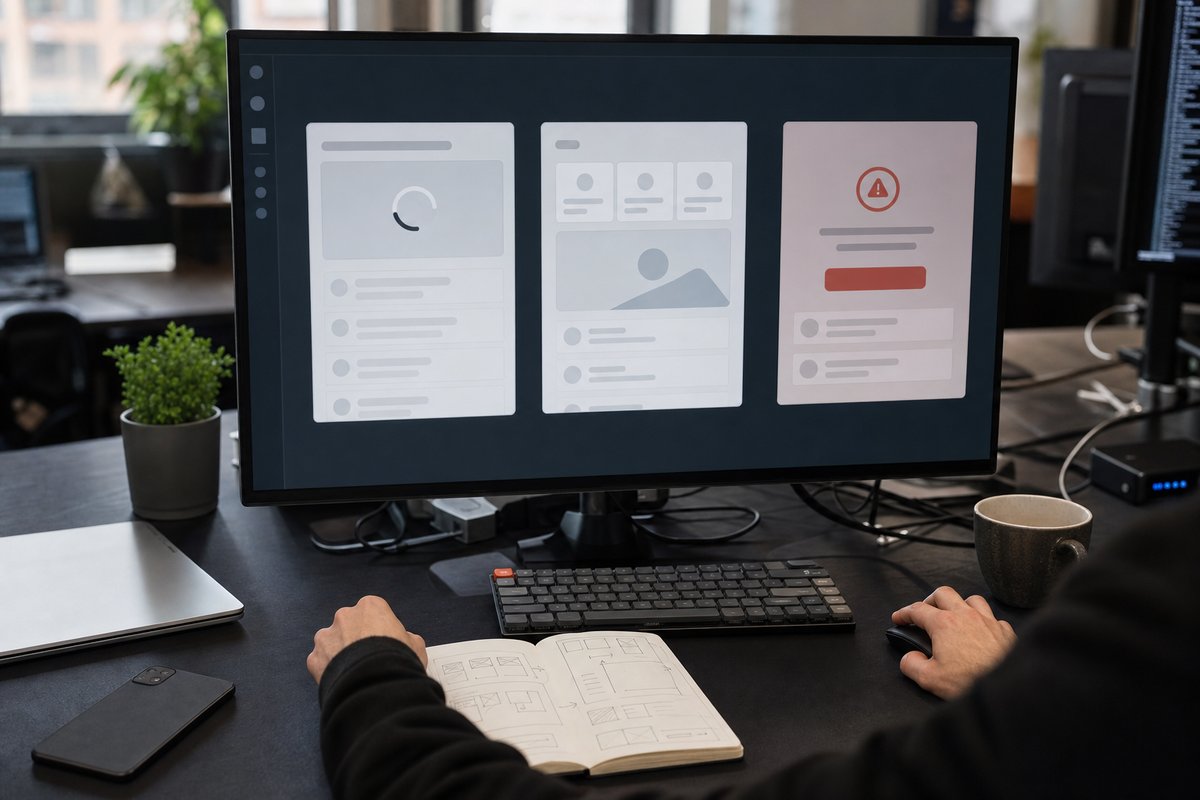
Why these states matter more than most teams expect
When people talk about product trust, they usually jump to security, uptime, or pricing. Those things matter. But day to day, trust is often built in much smaller moments: when a page is loading, when a table comes back empty, or when something breaks and your app has to explain itself.
It’s easy to wave those off as edge cases. They’re not. They’re the exact moments when users pause and wonder, even briefly, “Did this work?” “Did I do something wrong?” “Can I rely on this thing?”
Loading, empty, and error states are where your product shows its manners. A polished happy path is nice, sure, but a calm, clear response when something is slow or missing does more for confidence than another gradient button ever will.
For small B2B teams, the stakes are higher. Your users aren’t poking around for fun. They’re trying to approve orders, onboard customers, reconcile data, submit claims, or get through a workflow before a deadline. If your app gets vague right there, trust drops in a hurry.
Loading states should answer one question: is the system working?
A spinner by itself rarely answers that question. All it really says is, “Something might be happening.” Give it a few seconds and that starts to read more like, “maybe this thing froze.”
A good loading state gives the user context. What is loading? How long might it take? Can they keep working? Did the click register? Basic questions, but a surprising number of apps leave them hanging.
What better loading states look like
If a grid is fetching records, show a skeleton layout that matches the final structure. If a report takes time to generate, say that directly: “Building your report. This can take a minute for larger date ranges.” If a button starts a background process, change the button state to “Submitting…” and disable duplicate clicks.
Products like Stripe, GitHub, and Microsoft 365 usually handle this well. You can tell when an action has started, what part of the page is still catching up, and whether you should wait or move on. That kind of clarity lowers stress.
There’s an engineering upside too. Clear loading states cut down on repeated clicks, duplicate submissions, and support tickets that begin with “it didn’t do anything.” In my experience, that alone justifies the work.
Choose the right loading pattern for the job
Not every wait should look the same. A full-page spinner for a tiny filter change feels clunky. On the flip side, a subtle inline shimmer is the wrong call when the whole workflow is blocked by a long-running process.
- Skeleton screens work well when the layout is known and content is on the way, like dashboards, cards, and tables.
- Inline loaders fit small actions, like refreshing one panel or saving a field.
- Button progress states are best when the user just initiated an action and needs confirmation that the click registered.
- Progress bars or step indicators help when a task has real duration, like importing a CSV, syncing records, or provisioning an environment.
- Status messages with background processing are useful when the user doesn’t need to sit and watch, like “We’re processing this now. You can leave this page.”
The pattern should match the user’s risk. If the action could create duplicates, trigger billing, or change records, be extra explicit. Silence is how people end up clicking twice.
One perspective teams often miss: loading states shape perceived performance
Sometimes you can’t make a process much faster—at least not yet. Maybe you’re waiting on a vendor API, a SQL query, or a document conversion service. Still, you can make the experience feel a lot more trustworthy.
Perceived performance isn’t fake performance. It’s communication done well. If users can see the shape of the page, know their action was accepted, and understand what happens next, they’re usually more patient. That’s one reason thoughtful UI often hides complexity without hiding work. The system can be doing a lot behind the scenes without leaving the user stranded.
Empty states should tell the truth about what “nothing” means
An empty state isn’t just a blank screen with an icon and “No data found.” That message may be technically accurate, but it still tells the user almost nothing.
Empty can mean a bunch of different things. Maybe the account is brand new. Maybe the filters are too narrow. Maybe the integration hasn’t run yet. Maybe the user simply doesn’t have permission to see the records. Those are different situations, and they need different explanations.
Flatten all of that into one generic message and users are left to diagnose the problem themselves. Most won’t bother. They’ll just assume the app is broken—or at least kind of a mess.
There are at least four kinds of empty states
These are worth separating in both design and implementation:
- First-use empty state: There’s no data yet because the customer hasn’t started. This is a setup moment.
- Filtered empty state: Data exists, but the current filters returned nothing. This is a search refinement moment.
- Permission-based empty state: Records may exist, but this user can’t view them. This is an access clarification moment.
- Dependency empty state: Data should appear after an import, sync, or integration. This is a system status moment.
Those aren’t cosmetic differences. They reflect different product situations, and they should lead to different copy, actions, and support paths.
Good empty states give the user a way forward
If it’s first use, offer the next setup step. “No customers yet” should be followed by “Import a CSV” or “Create your first customer,” not a dead end. If filters returned nothing, include a quick reset. If the issue is permissions, say who can help: “You may need access from your workspace admin.”
Notion, Airtable, and Linear all handle this reasonably well in their own ways. They don’t just announce emptiness. They give it context. That’s the difference between a UI that feels thoughtful and one that feels unfinished.
For B2B products, empty states can also reinforce the workflow. If your product depends on integrations, approvals, or scheduled imports, say that plainly. “No invoices yet. Your ERP sync runs every hour.” One line like that can stop a lot of unnecessary panic.
Error states are where trust is either repaired or lost
Errors happen. APIs time out. Tokens expire. Files are malformed. Users paste the wrong value into the wrong field. Nobody expects software to be perfect.
They do expect honesty and direction.
A bad error message creates three problems at once: it interrupts the task, hides the real cause, and makes the user feel responsible for a system problem they can’t fix. We’ve all seen versions of this: “Something went wrong.” Okay... and now what?
What a useful error message needs
Most error states should answer four things in plain English:
- What happened
- What it affects
- What the user can do next
- Whether the system saved any progress
For example, “We couldn’t save your changes because the connection to the server dropped. Your edits are still on this page. Try again.” That’s not fancy writing. It’s respectful writing.
And if the problem is on your side, say so. “Our document service is temporarily unavailable” lands much better than wording that implies the user messed something up. Blame matters more than teams sometimes realize.
Not all errors deserve the same treatment
A validation error on one field should be immediate and local. A failed page load might need a retry option and a support reference. A payment problem may need more caution and more detail. A background job failure may require both a UI message and an email follow-up.
Here’s the practical way to think about it: size the error state to the consequence. If the user can fix it in one step, keep it close to the field or action. If the issue blocks a workflow, give it more space and more guidance.
Authentication deserves special attention
Sign-in is one of the fastest ways to lose a new customer’s confidence. If your identity flow bounces people between your app, Microsoft, and a half-clear callback screen, the product feels shaky before they’ve even started using it.
A thoughtful sign-in error experience should explain whether the issue is an expired session, missing invitation, tenant mismatch, or permission problem. Those are very different cases. A lot of apps still squash them into one generic login failure message.
If you use Microsoft Entra ID, this is worth tightening up. Small copy changes and better redirect handling can make enterprise identity feel a lot less intimidating.
The backend matters just as much as the UI
Here’s the part some product teams underestimate: you can’t design great loading, empty, and error states if your application doesn’t expose meaningful states.
If the frontend only gets “pending” or “failed,” there’s only so much it can say. If your APIs return structured reasons, processing stages, retry guidance, and correlation IDs where appropriate, the UI can be dramatically more helpful.
This is where product design and engineering have to meet in the middle. The interface can only explain what the system actually knows.
Observability makes these states better over time
Good state design isn’t one-and-done. You ship what seems reasonable, then learn where users still get stuck. Maybe the loading state shows up too often because one endpoint is slow. Maybe a “no results” screen is really masking a sync failure. Maybe a retry button is covering up a token refresh bug.
That’s why customer-facing workflow monitoring matters. Tools like Azure Application Insights can show you where requests stall, where exceptions cluster, and which user flows deserve a closer look. You’re not just monitoring servers—you’re monitoring trust.
And yes, there’s a trade-off. Instrumentation takes effort. Naming events well takes discipline. Without that visibility, though, teams end up arguing from anecdotes instead of fixing the parts of the experience that quietly cost them adoption.
How to review your product like a user who doesn’t trust it yet
One of the best exercises is to stop reviewing only the happy path. Walk through the product assuming the user is new, a little skeptical, and under time pressure.
Try common scenarios. Upload a bad CSV. Load a page on slow Wi-Fi. Filter a list down to zero results. Expire a session. Disconnect a dependency in a test environment. What does the product say? Is it calm? Specific? Does it help you recover, or does it just shrug?
If you want a simple review checklist, use this:
- Does every user-triggered action show immediate feedback?
- Do loading states explain what’s happening when the wait is noticeable?
- Do empty states distinguish between first use, no results, permissions, and missing dependencies?
- Do error messages tell the user what happened and what to do next?
- Does the UI preserve work where possible?
- Can the team trace these states in logs and telemetry?
You don’t need a giant redesign to improve this. Usually the wins come from tightening copy, exposing better backend status, and replacing generic placeholders with messages that match reality.
Small details, real trust
Users notice when software respects their time. They notice when a save action confirms itself, when an empty screen points to the next step, and when an error message sounds like a person instead of a stack trace—especially with better branding.
That’s really the point. These states aren’t decoration around the “real” product. In the moments when confidence is fragile, they are the product.
If you’re deciding where to spend design and engineering time this sprint, pick one workflow your customers use every day. Map its loading, empty, and error states from start to finish. Then rewrite the unclear parts, add the missing status signals, and instrument what you can’t yet explain. That’s a practical way to make trust visible.